A large share of day-to-day business operations depends on servers that must run continuously. Most teams have little visibility into the details until something goes wrong. Failures happen, however, and their financial impact can escalate faster than you’d think. Industry estimates place the cost of downtime between $10,000 and well over $1 million per incident. The final figure depends on how critical the affected systems are and how long recovery takes.
Those numbers can make any company think twice about its recovery readiness. Prevention helps, but it is only half the job. Success also depends on knowing how teams respond when a failure hits and how they restore systems afterward. Sometimes, restoring means starting from a blank slate on a new machine.
Bare metal recovery rebuilds entire environments on new or clean hardware in a controlled way. In this blog, we’ll explore how bare metal recovery works and where it fits within a broader data protection strategy. We’ll also cover what organizations should consider when they prepare for recovery scenarios.
Understanding the Basics of Bare Metal Recovery
Bare metal recovery is a method of restoring a system from scratch onto new or wiped hardware. It does not rely on any existing operating system or software environment. It captures a full system image of the OS, drivers, applications, configurations, and data. Then it redeploys that image on a new machine. You don’t reinstall components one by one or piece a system back together under pressure. Instead, you rebuild the entire environment in a state that mirrors the original as closely as possible. That can be exactly what you need when a server fails outright or becomes unusable for other reasons. The restoration brings back applications, files, data, and the operating system exactly as they were. Bare metal recovery is more common with Windows, but it works with all operating systems.
The bare metal recovery process is image-based, so it reduces the risks that come with manual rebuilds. Teams also hit better RTOs. It allows recovery onto different hardware, which matters when identical replacements are unavailable.
Understanding How Bare Metal Recovery Works
The Data Recovery Process
Bare metal recovery is built around recreating a complete system from a single image. First, the team captures that image in advance, including the operating system, installed applications, system settings, and all associated data. That snapshot becomes the reference point for recovery. Alongside it, the team prepares bootable recovery media that contains the recovery environment and the information needed to locate the backup.
During an incident, the team starts the failed or replacement machine from this external media, since the target system has no usable OS. The recovery environment loads independently and connects to the backup location, whether on-premises or remote. From there, it deploys the system image onto the hardware, reconstructing partitions, restoring files, and reestablishing the original configuration.
Many solutions also account for hardware differences by injecting the right drivers during the process. When the restoration is complete, the team restarts the system and validates that everything behaves as it should.
The Technology
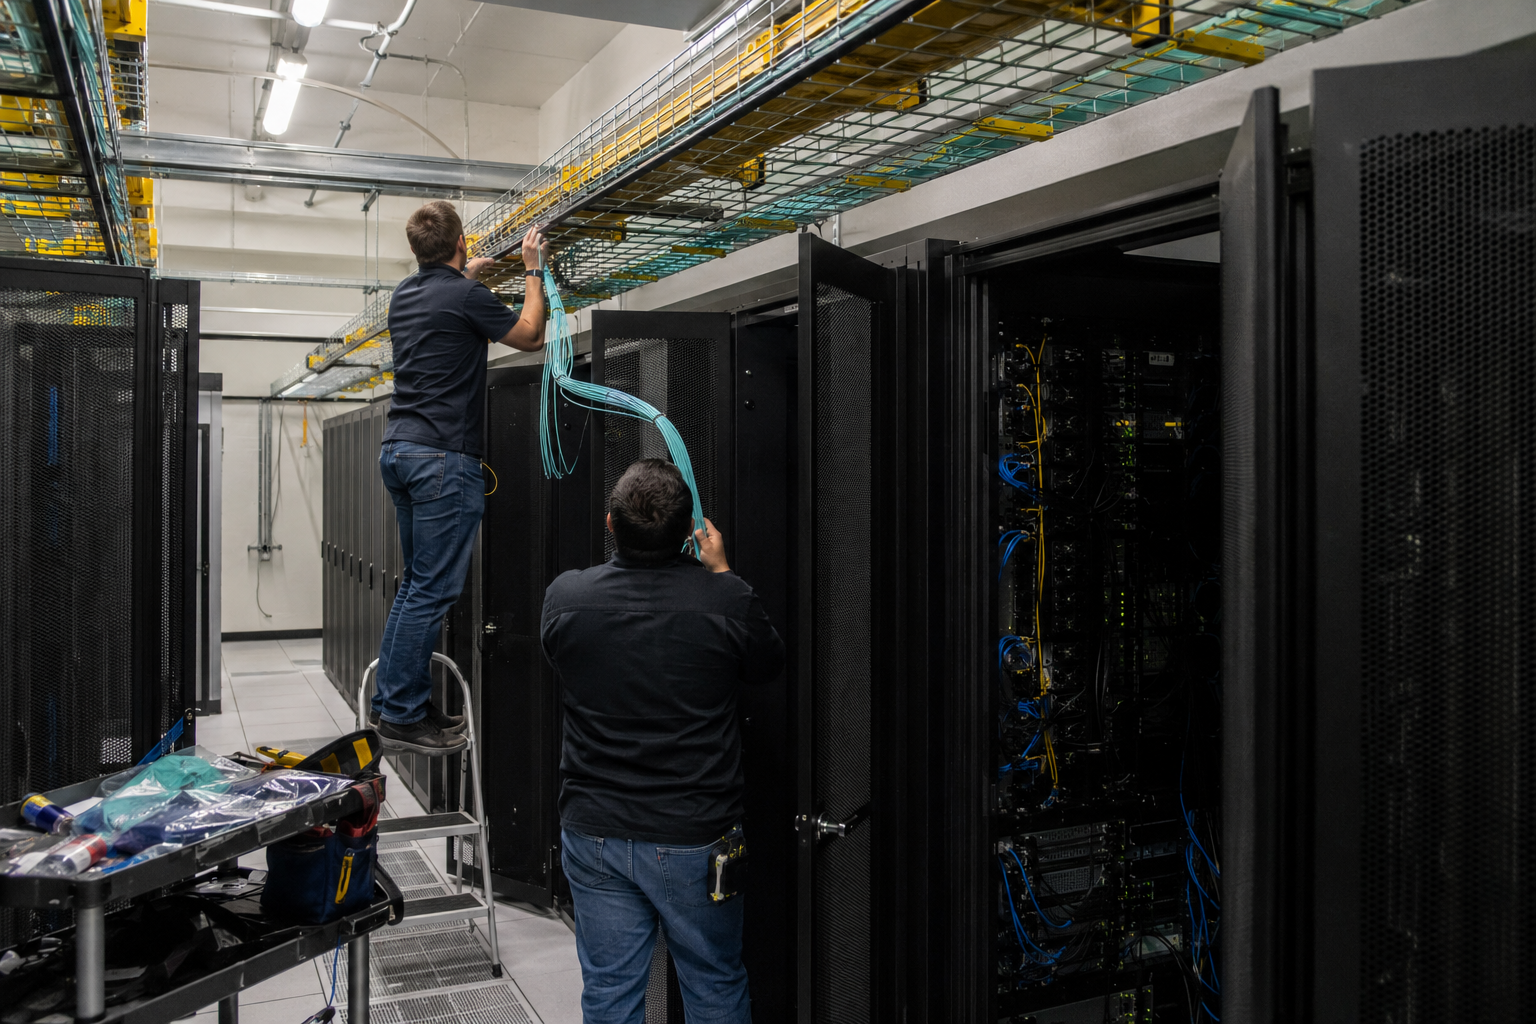
Bare metal recovery builds on disk imaging technologies like Windows Server Backup, which create and manage full system snapshots. Dedicated backup platforms handle these snapshots and automate image creation, storage, and retrieval. Organizations can store the images in several places, including local storage arrays, network-attached systems, and cloud storage. The right choice depends on their data protection strategy. Recovery can start from bootable media, like a USB drive. Larger environments often rely on network-based booting, so they can streamline recovery across many systems. In more advanced setups, teams use virtualization technology to restore images directly into virtual machines, which speeds up recovery and testing. Cloud-integrated solutions go further, because they let teams retrieve and deploy system images without depending on a single physical location.
When Should an Organization Use Bare Metal Recovery?
Organizations use bare metal recovery when they can’t reliably repair a system and have to rebuild it from scratch. This can happen after hardware failure, severe data corruption, or a security breach that leaves the operating system untrusted. Restoring individual components can be slow and uncertain, so organizations turn to a full system restore in these situations.
However, organizations also use bare metal recovery in planned scenarios, especially during hardware upgrades or infrastructure changes. Teams sometimes have to move systems onto new servers or different environments while keeping configurations intact. In these cases, they can redeploy the existing system as a complete image instead of reinstalling and reconfiguring everything manually.
The common thread across these use cases is control and consistency. Bare metal recovery lets organizations restore a known-good system state in a structured and secure way.
Benefits of Bare Metal Recovery
When done properly, bare metal recovery is a practical way to rebuild systems fast without reconstructing every component manually. Its main advantages include:
- Fast and efficient recovery. BMR can shorten recovery because it restores the entire system environment at once. Teams don’t have to reinstall the OS, apps, settings, and data separately. Many BMR tools also guide IT teams through each recovery step, so the process stays controlled and easy to manage.
- Flexibility: BMR fits many recovery scenarios, especially those that involve hardware changes such as failures, server replacements, and infrastructure upgrades. Teams can usually restore systems to different hardware configurations, so they have more options when the original machine becomes unavailable.
- Cost benefits: The faster you restore a system, the less downtime the business is likely to experience. Less disruption translates directly into lower recovery costs. Bare metal recovery also saves IT teams from unnecessary manual rebuilds, so they can focus on more important tasks. Full system restoration can reduce the financial risk of data loss as well.
Another overlooked advantage is less operational complexity during incidents. Recovery processes become more standardized, and teams don’t have to make as many decisions under pressure. That structure can make a meaningful difference in how smoothly recovery efforts unfold.
Possible Challenges During Bare Metal Recovery
Bare metal recovery is reliable when teams prepare everything properly, but the process can expose a few weak points. These usually surface under the pressure of a real incident. Most challenges don’t come from the recovery itself. They come from the dependencies around it, such as how teams create and store backups and how those backups align with the target environment.
- Hardware compatibility issues: Restoring a system image onto different hardware can introduce driver mismatches and configuration conflicts. Many tools try to handle this automatically. Still, differences in storage controllers or network interfaces can cause boot or stability issues.
- Backup integrity and currency: The recovery is only as good as the image you restore. If backups are outdated, incomplete, or corrupted, the restored system may lack recent data or fail completely. This becomes especially problematic when backup verification isn’t part of the regular routine.
- Recovery environment dependencies: Bare metal recovery relies on external components like bootable media, network access, and storage connectivity. If one of these pieces fails or isn’t available during an incident, recovery can slow down or become difficult.
These challenges don’t make bare metal recovery unreliable; however, they do highlight the importance of preparation. Testing recovery workflows, validating backups, and aligning hardware expectations in advance make a big difference.
Important Bare Metal Recovery Measures
The key bare metal recovery measures are really about preparation. The recovery itself matters, of course, but most successful BMR outcomes depend on decisions teams make before the failure occurs. It works best as part of a broader data protection strategy with consistent backups, regular testing, and a clear recovery plan that teams can easily follow.
Key Measures
- Create complete system image backups
Bare metal recovery depends on full system images, and file-level backups are not enough. The images should include the operating system, applications, configurations, drivers, and data, so you can restore the entire environment as fully functional. - Define clear backup schedules
Each organization has to decide how often to capture system images, based on how much data it can afford to lose. This means more frequent backups for critical systems, in line with the organization’s RTO. - Store backups in more than one location
A backup stored only on the affected machine or local network can become useless during a larger outage. Store copies in several locations, such as secure off-site locations, the cloud, or isolated backup environments. - Prepare bootable recovery media
Since BMR usually starts without a functioning operating system, teams need ready-to-use recovery media, like a USB drive, recovery disk, or network boot environment, to launch the recovery software.
Key Measures for Testing and Planning
- Verify backup health
A backup that exists but can’t be restored is essentially a false safety net. Organizations should test whether images work before they need them in a real incident. - Test the recovery process
Testing helps teams identify driver issues, storage problems, network access gaps, and documentation weaknesses. They can then solve these issues before a real outage hits. - Document the recovery workflow
Documentation should explain where backups live, how to access recovery tools, which systems have priority, and who owns each step. - Account for hardware compatibility
If you can restore systems to different hardware, confirm that the recovery solution supports driver injection or hardware abstraction. This matters most when identical replacement equipment isn’t guaranteed. - Align recovery planning with business priorities
Prioritize critical workloads based on their operational role, downtime tolerance, and Recovery Time Objective.
Data Restoration Best Practices
When a system goes down at the infrastructure level, the real bottleneck usually isn’t the tooling. It’s whether the recovery process is already clear and workable. A pre-defined way of handling incidents, already prepared and practiced, makes recovery much faster than piecing everything together in the moment. A structured set of ready-to-use practices gives teams a reliable starting point, so they can act without second-guessing each step.
Schedule regular, consistent backups
Recovery starts with having something reliable to restore from. Backups should follow business requirements, not convenience, and align with defined recovery objectives. It’s also important to verify that backups complete successfully and capture full system states, especially for bare metal recovery scenarios.
Document processes and technology details clearly
Documentation should cover where backups live, how teams access recovery tools, what dependencies exist between systems, and which configurations are critical. It should include procedural steps and technical context, so teams understand not just what to do but why it matters.
Simulate recovery scenarios regularly
Testing recovery under controlled conditions exposes gaps that aren’t visible on paper. Simulations help teams validate backup integrity, confirm access to recovery environments, and identify bottlenecks in the process. They also build familiarity, so when a real incident occurs, the steps already feel like routine.
Update and refine standard operating procedures (SOPs)
Ideally, recovery processes shouldn’t stay static. Many changes can happen over time, so teams need to revisit SOPs regularly. They should feed lessons learned from tests or real incidents back into the process, which improves clarity and removes unnecessary friction over time.
Define roles and responsibilities in advance
Clear ownership prevents confusion when time is critical. Teams should know who initiates recovery, who validates systems, and who communicates status updates. Structure helps reduce the delays that uncertainty causes.
Keep Your Data Safe Across Environments
Staying prepared comes down to treating data protection as a continuous practice. The list of risks keeps growing. Beyond hardware failures, cyberattacks, natural disasters, software corruption, and human error can all disrupt systems. Businesses need a clear, structured way to protect systems and recover data. Approaches like bare metal recovery can give your organization a safety net for challenging situations. As part of a complete BMR strategy, cloud-based Backup-as-a-Service (BaaS) solutions can help you streamline recovery and meet RTO and RPO objectives.
At the end of the day, preparation is about clarity. Know how quickly systems need to come back online. Understand what data you can’t afford to lose. With the right mechanisms in place, recovery becomes far more manageable, even when the situation itself isn’t.
To learn more about recovery options and solutions, contact us today.